n8n template
AI Token Cutter
Cut your AI bill without rebuilding your flows. One n8n workflow you call instead of the OpenAI or Gemini node: repeated requests are answered from a cache, easy tasks go to the cheap model, hard ones to the strong model with low reasoning, long emails are trimmed, and every call is logged with what it cost. Works with GPT-6.1 Sol, GPT-6 Luna and GPT-6 Astra, or Gemini.
🆕 New in v1.2: Astra mode. OpenAI says GPT-6.1 Sol gets near Astra for a fifth of the price. If GPT-6 Astra runs your flows, change two fields: the easy work goes to Sol and only the hard work pays Astra prices. Astra’s prices are already in the cost meter. Free update for everyone who bought it.
Who it’s for
Automation freelancers, web developers and agencies whose n8n workflows call OpenAI or Gemini all day, and anyone who wants to see what each AI call really costs.
What you get
- AI call (OpenAI or Gemini): a drop-in sub-workflow with cache, router, prompt slimmer, backup model and cost meter. Your flow gets the answer, the model used, the tokens and the cost in dollars.
- Weekly cost report and alerts on Telegram: what you spent this week vs last week, by model and by project, plus an alert when calls fail or you pass your daily budget.
- Batch queue (OpenAI, 50% off): jobs that can wait go to OpenAI’s Batch API at half price; results land in a Data Table.
- ▶Try it: 6 sample requests that show the cache, the router and the cost of each call.
- Step-by-step PDF guide, the 100 test requests and the measured results. English and Spanish versions.
Measured, not promised
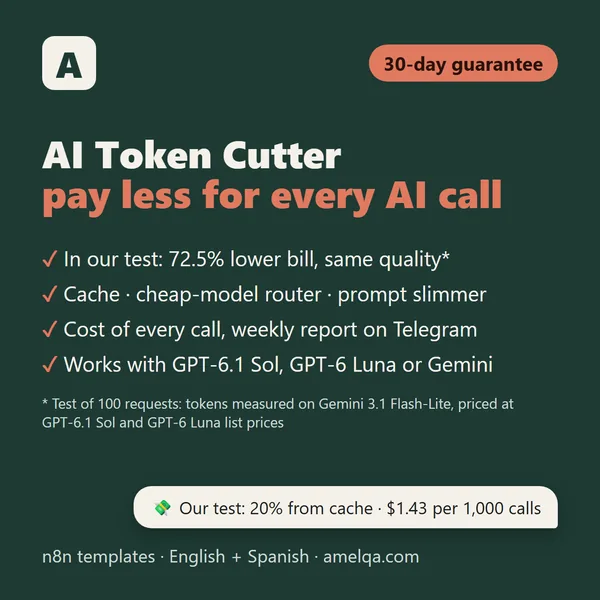
- 72.5% lower AI bill on 100 typical automation requests: $5.20 → $1.43 per 1,000 requests. Tokens measured with Gemini 3.1 Flash-Lite, priced at OpenAI’s list prices for GPT-6.1 Sol and GPT-6 Luna.
- 59.5% fewer tokens in the same test (48.5% less input, 65.9% less output and reasoning).
- Without the 20 repeated requests (no cache hits at all): 67.5% lower bill, 52% fewer tokens.
- 20 of 100 answered from the cache for 0 tokens; 60 sent to the cheap model, 20 to the strong one.
- Quality kept: 67 of 68 answers with a known result were right through the kit, vs 66 of 68 sending everything to the strong model.
How we measured (2026-10-03, n8n 2.41.6, the workflow you get): no OpenAI model was called. Every request, with and without the kit, was answered by Google’s Gemini 3.1 Flash-Lite (free tier): reasoning “medium” for the baseline, like GPT-6.1 Sol’s default; “low” for the strong tier and no reasoning for the cheap tier through the kit. The dollars are those measured tokens × OpenAI’s public prices for GPT-6.1 Sol and GPT-6 Luna (developers.openai.com, read on 2026-10-03). GPT-6.1 Sol and GPT-6 Luna will use different token counts, so your saving will differ: the weekly report shows yours.
Why it is different
- No new infrastructure: cache and logs live in n8n Data Tables. No Redis, no database, no gateway subscription.
- The router does not spend AI: simple rules you can read and edit in one Settings node. When the cheap answer looks weak, the strong model answers instead.
- Never silent: if a model fails it asks the other one; if both fail your flow gets ok: false and you get a Telegram alert.
- Every price is editable, all in one place; reasoning is billed as output, so it uses low by default.
What you need
n8n 2.41 or later (n8n Cloud or your own), an OpenAI or Gemini API key, and a free Telegram bot for the report. About 15 minutes to set up. Use it in your business and in your clients’ projects.
AI Token Cutter
$49 one-time
30-day guarantee, no questions asked: if it isn’t right for you, for any reason, you get your money back. How refunds work.
Get it on GumroadYou may also like
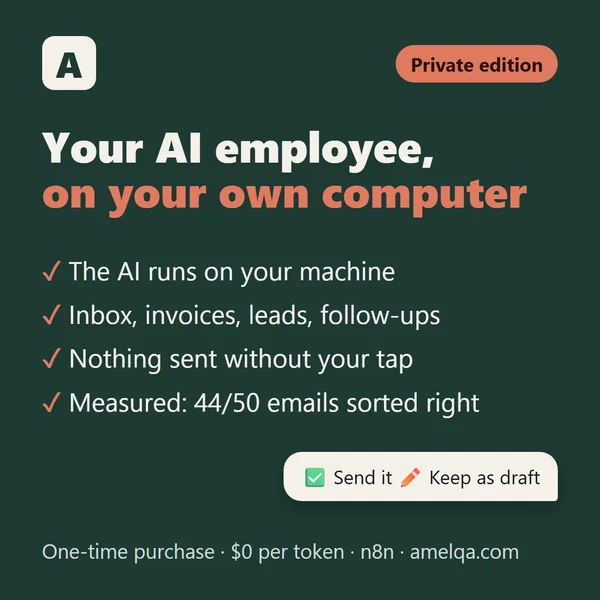 n8n template pack · local AIAI Employee · Private EditionAll 5 roles, with the AI on your own computer (Ollama or LM Studio). No AI cloud and no per-token bill.$199
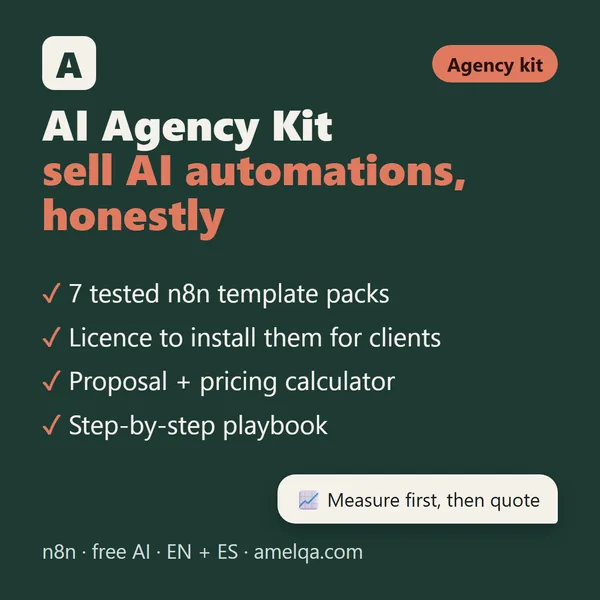 Kit · 7 template packsAI Agency KitIncludes the full AI Employee ($149 on its own), plus 6 more client-ready n8n template packs, a playbook, a proposal template and a pricing calculator.$99
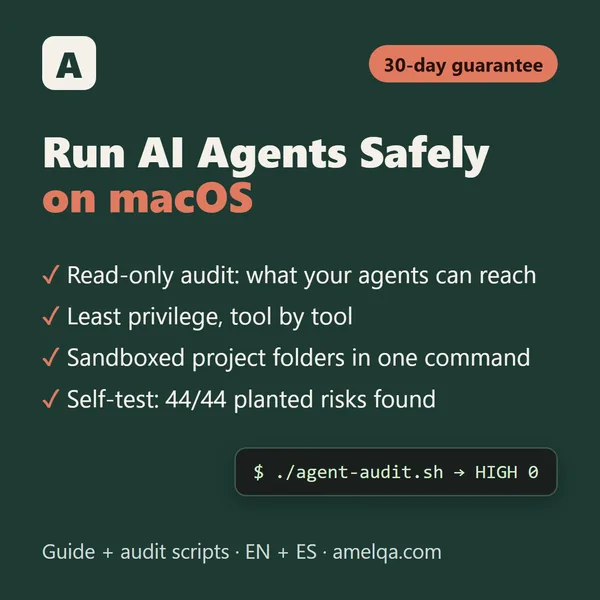 Playbook + audit scriptsRun AI Agents Safely on macOSA permission playbook and audit scripts, so your agents keep working without giving your terminal Full Disk Access.$19
← All templates · amelqa.com home
Reselling the files is not allowed. OpenAI, GPT, Gemini, Telegram and n8n are trademarks of their owners; no affiliation with Amelqa.